David Weinberger published a new book, Beautiful Particulars (How AI’s Attention to the Smallest of Differences Is Reshaping Our Biggest Ideas), which was published last week by MIT Press. The title Beautiful Particulars already made me want to have and read it. Bought both the paper and electronic version, and the former should arrive in a few days. Ever since I first met David, at the first European blogger conference in Vienna, I’ve appreciated the depth and wit he brings to conversations. Very much looking forward to reading this, as judging by the blurb and tags, it ties to my personal interests, my personal sense of beauty, and to the work on ethics of AI my company is doing so much of.
Category: Learning
 subscribe to this category with rss
Y’s First Anki Spaced Repetition Deck
Y is currently learning European countries and their capitals for school. Of the 45 country/capital combinations to be learned on a blind map, 24 will be tested next week, and the remaining 21 two weeks later. Self study, or with our help, can mean that less well remembered combinations don’t get the attention they need. And where we help she only provides answers and does not see the writing of a name.
Y also likes to practice more than what we can give her in time.
This morning I thought that this was a good option to create a card deck for spaced repetition for her, and install Anki on her (Linux) laptop.
Anki’s data structure is not hard, and the material in this case has an even easier structure (numbers as map reference, country names and city names).
The blind map however was a bit harder to include usefully. The map is not very large, with small numbering. On top of which came that the teacher had made three mistakes numbering some of the Balkan countries. Two were corrected with pen by Y, one was uncorrected. Scanning the map also gave a not very satisfying result in terms of contrast, and there was a folding line through the map as well.
 The scan of the map, with manual corrections
My graphical skills are non-existent, so I started up Claude to improve the image in terms of contrast and legibility. It did, after which I went through the map to verify no mistakes were introduced.
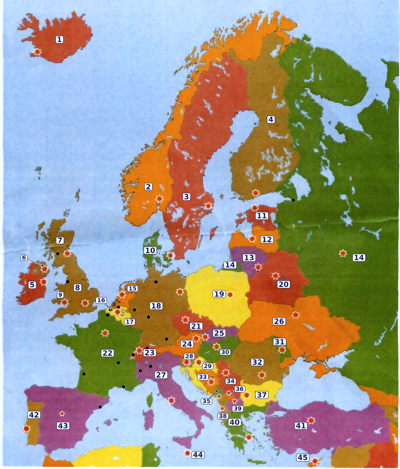
The map with improved contrast and the numbers all replaced in black lettering in a white box.
With the map improved I used it in the template for the Anki cards. I made a note type ‘Europe map’ with the three fields I mentioned, and imported the list of 45 countries into it. I also made an additional note type, namely for groupings of countries. Just a few for now. Creating chunks like that (the Baltics, the BeNeLux, Scandinavia, UK, the Irish island) is another way to make memorising easier. Chunking was not part of how the material was handed to Y, but something I added. Especially chunking the three Baltic countries is useful to tell them apart. They are positioned north to south in alphabetical order.
I created three card types for each country and capital.
- Which country is number X on the map, and what is its capital? (and the grouped version ‘Which countries are the numbers X,Y,Z on the map?)
- What is the capital of [country]?
- [capital] is the capital of which country?
All three card types show the map image as well.
Getting Anki properly installed on Y’s Linux Mint laptop was the biggest hurdle it turned out. The package manager on Linux Mint is tied to outdated versions of Anki, so I had to install it through the terminal after first manually installing a range of additionally needed libraries. The Anki documentation helped. It shows once more how Linux is not a consumer ready OS (mostly because of the variety of Linux distributions, no way any app builder can easily deliver one-click installers for all of them.)
When I picked up Y from school this afternoon, I explained what I made as we cycled home.
She immediately tried it out. In the next few days we’ll see how it works for her.
Comparative Literature As Core Need In Desk Research and AI As Tool
A year ago I read Libraries of the Mind by William Marx, and some of it is still very much on my mind ever since. Particularly what William Marx called ‘dark matter’ literature, which exists but you don’t have access to. E.g. because it’s in a language you can’t read, or material you don’t know how to search for. Material that is invisible from your own viewing position. Because that invisibility is easily accepted as proof of absence of such material, rather than proof of limitations on your own toolset and agency preventing you to find it, such resources will be generally ignored.
Still, many questions have global aspects. Our information networks, our trade routes, our dependencies are truly global. Because of it many of our issues, including climate emergencies, are global in both their roots and consequences. We all suffer from small earth syndrome these days, as I phrased it in 2010 at the SHiFT Conference, where everything anyone of us does reverberates around the world because we are continuously bumping into real global limits, Club of Rome style.
The same is true in reverse: many of the pathways to agency, to resolution and mitigation are global in nature too, or at the very least need us to look at available information, thinking, and perspectives globally as well.
‘Global’ therefore is not to be taken here as a level of abstraction or aggregation, which erodes your own place in it and throws out your own localised experience and stories, but global in the scope you yourself default to when it comes to who you see as part of the whole, as worthy of consideration and/or empathy, as affected by your choices and actions. Global also not as an equaliser or one-size-fits-all thing, unmooring identities e.g., but using differences as an energy source and as potential for creativity. In any situation there are boundaries between groups and narratives. Power differences, and identities resting on opposing or similar assumptions, differences in who has legitimacy or standing in which situations and issues, differences in who has or is afforded agency and in which ways, all abound. All these differences are potential energy to tap into.
Put together it spells to me that when I am doing some deskresearch shining a better light on literary ‘dark matter’ becomes much more important. Are there any francophone resources, Nordic authors, Eastern European authors, hispanic movements around an issue I am exploring? Yes, the scientific world largely uses English as lingua franca, but language areas also have their own spheres outside of it. Look in any French or German book store for instance and compare the shelves on topics of your interest to e.g. a UK book store. They also all have their own scientific publishing channels. That is all still within a largely overlapping European context. What about ongoing Chinese perspectives, Southern-American movements, the various spheres of discussion on the African continent, and across Asia? Those will be almost completely invisible to me on any topic, when my own tools are limited to my personal language skills and the general anglo-american bias in online search tools.
Enter AI tools as a middle way, along the lines of what Jeremy Cherfas wrote recently. He posits his own AI use for “things that you perhaps could manage on your own, but that would take too long to be worthwhile.” And while “there are plenty of areas in which I feel that AI could never be appropriate” he “was happy to use generative AI to extend my capabilities” where that strengthened his own efforts andv where outputs are for his personal or intermediate use in his own work processes.
When I ask e.g. Claude about a book and its message, and to help build a more syntopic reading list around something, what you get is a few English titles, as would be expected given their origin. Adding my own language skills, it will add a few other resources. Any extension beyond that you need to directly ask about: is there anything in e.g. Nordic countries, are there traces of similar discourse in China etc.? In steps what will emerge is a fuller list of pointers. Many of those I won’t be able to read directly, but I can circle around them, e.g. through secondary sources, by machine translating parts etc. I’ve noticed that to do this, to go beyond middle of the road AI responses, I need to build it up, in steps. Which is something I can put together as a recipe and feed into Claude.
I won’t speak or read Chinese, Igbo, Swedish or Polish in my lifetime. But I can ferret out resources and what they may tell me this way.
Today I started reading in Rest Is Resistance by US author Tricia Hersey, it was mentioned to me recently in the context of maintaining hope or optimism while also feeling dread and despair about the state and direction of the world, alongside Rebecca Solnit’s Hope in the Dark, and the Dutch title ‘Optimism without hope’ by Tommy Wieringa. Turned out I already bought it in 2023. I wondered about other similar or adjacent texts and used Claude in the way described above. First came a list of mostly English resources, and one German, most of which I was already aware of. Then following up a handful of francophone resources, nordic ones, and hispanic ones came up, which unearthed a link to Latin-American texts I had already explored a few years back related to a local legal initiative in the Netherlands w.r.t. climate adaptation. It struggled with providing pointers to resources from the African continent, but ultimately did. Further prompting brought both official and grass roots perspectives from China, more francophone resources from the Caribbean world, and also more potentially relevant African and Indian resources.
A first approximation of a syntopic approach like this is no output in itself, but a starting point, meaning I now have more to do than if I had been satisfied with just the titles I already own or am already aware of. But I am casting a wider net, even if what the net brought up may not all be equally useful, it pushed me to look further and broader. It stretches my Library of the Mind.

The University of Maastricht Library, which I walked by a week ago. Its collection limited by necessity, like our global digital library is limited by our tooling.
Not Fully Digitally Sovereign Versus Increasing Cost of Leaving
In a session earlier today the deployment of a tool was discussed in an organisation’s information environment that is otherwise fully dominated by Microsoft products. After a presentation a director asked “if we add this tool to our (Microsoft) mix, aren’t we working in opposition to our wish for more digital autonomy and digital sovereignty”? The answer was “well you are already using Microsoft tools everywhere so sourcing this one tool from someplace else won’t change your autonomy in any way.”
I disagree. This is the pitfall of “it’s only worth changing if we can get from here to a mythical ideal situation in a single easy step, otherwise we’ll stay put”.
Indeed, opting to source a single tool outside of the walled garden you’re in does not change anything about you being in that walled garden as such. But adding a tool within the walled garden does make it harder still to leave that walled garden in the future. It increases your cost of leaving once more.
You have to begin somewhere if you want to move out of monopolies under foreign jurisdiction outside your democratic control, that can determine what’s on your screen and in your inboxes. Not adding to the problem is one step easily made, because it does not require you to change anything in your current way of working, just to apply different decision criteria upfront when adding something.
The Threefold Personal KM Zine
At the European PKM Summit the past two days, Frank Meeuwsen ran a continuous atelier where people could make their own ‘zines and lino cuts. A welcoming space to make something by hand at an event full of inspiring but abstract conversations and talks.
A simple ‘zine folded from an A4 paper provides six small pages, including the front and back. That forces you to be to the point.
I thought of a posting I wrote a little over a year ago, about how personal knowledge management is personal in three ways, and that generally you should always take the P in PKM even more personal than you’re already doing.
Three points to bring across sounded short enough to lend itself for a message in a zine.

The P in PKM is 3 fold personal. (jouw = yours in Dutch)

First, it’s your personal system. You take it with you. It enables and anchors your personal autonomy, and allows you to own your own learning path

Second, it’s your personal knowledge, building on your own curiosity and interests, with your associations, in your language. Your personal network of meaning.

Third, it’s your personal system. Your emergent structures, following your logic, stemming from your personal methods and workflows.

Personal KM is way more personal than you think. And still more.
The Vibe of Coding Personal Tools
Yesterday Martijn Aslander demonstrated the personal information tools he recently created. I came away inspired. Perhaps not by the tools as such, and more because of the pathways of thinking it opened. And because everything was so blazingly fast. All vibe-coded, as he has no coding skills himself.
I can see how the way his brain works is aided by the structure and availability of information his personal toolbox provides him. However, I myself would be more interested in shaping a personal tool like this towards being able to facilitate me in my processes and habits, as well as let me work towards actual outputs.
The Digitale Fitheid (Dutch language platform) community (Digital Fitness, the English language platform) has a monthly face-to-face meet-up in Utrecht, and yesterday was this year’s last. In the morning E had attended a session by Frank Meeuwsen on how to use Claude Code to quickly build something from scratch. In the evening I joined Martijn’s session on what he is calling his ‘Theta OS‘.
Some observations.
- Martijn’s Theta is mostly a dashboard on local information. It shows him lots of different pieces of information at a glance. Each of these things, hotel bookings, books, payments, tasks, quantified self measurements and more, can live and be accessed in their own little apps and silos, but he uses the dashboard to combine them in context. At the outset he said that having his own established ontology (in the information sense, not the philosophical) was a prerequisite. That sounds very true, as the purpose here is having an extremely personal tool. The value is in combining various information sources on purely personal criteria on the fly.
- His tool stack is sqlite (a lightweight database, installed by default on my Mac), with node.js (to run javascript), and regular html and css for the front-end using the local webserver on his laptop. I didn’t have node.js on my Mac, installed it now to be able to try some things.
- He is not a coder, so everything is vibe coded with Claude Code. And while maintaining that makes him able to quickly create things, he spent some 500 hours in Claude Code in the past months. Makes me wonder what he could have done in those 500 hours if he hadn’t used it. I do recognise that given his nature, a organised path of exploration and learning would not have been feasible, though might well have resulted in a similar proof of concept after 500 hours.
- Because of this he wasn’t really able to conceptually discuss the results other than what it does on the front-end and what it means to him. When asked about the architecture of the tool he therefore asked Claude Code to whip up a description.
- In working with Claude Code he did not feed it his personal information, but abstracted structures. E.g. to incorporate a CSV with personal information he would provide the structure and a bit of dummy data to get a parser or importer and change the database structures. Then use the importer for the actual data outside of Claude.
- To Martijn Theta is for surfacing and combining little pieces of data and information. He also uses markdown notes a lot (with Obsidian as viewer), but Theta keeps all the small pieces out of his notes. Only when he combines things into something more informational he brings it into his markdown notes. I find this distinction makes sense, as I am usually adverse to ‘make Obsidian do everything for me’ type of efforts. I use several tools that work on my Obsidian notes but do not attempt to be part of Obsidian. Largely absent yesterday was the other way around in the demo / discussion: getting small bits out of Obsidian into his dashboard.
- The entire thing as it is now is a tool that clearly and visibly had an evolutionary path, as opposed to a planned-for structure and design. This appeals to me a lot. It is the same with my own personal tools and system of notes. Others sometimes remark on how it would impossible for them to create something like it for themselves. Thing is, neither could I. The current state evolved over time, and does not lend itself to reconstruction. That this sense of evolution stands out to me after a few months of Martijn spending that 500 hours in total on his Theta OS too, to me is a strong argument in favor of his approach.
- This is reinforced by how he clearly builds intensively on his own structures and habits. As I often remark too, I am predictable to myself, and it means any software tool you build for yourself can make choices based on that predictability. If I want to save something I know which attributes I care about, and in which form I want to have them available. If I make a shopping list I know the order of the supermarket shelves of the store I’ll visit. If I’m near a Dutch railway station in the evening, it is most likely I intend to take a train home, that type of thing. The same is true for my information strategies. I know where I store my book notes and how, as I’ve been doing it for ages etc.
- Building on that predictability he makes functionalities in Theta highly contextual. If he bookmarks a LinkedIn profile, it means he wants a person note with a few distinct fields from the profile (e.g. current role and location), and bookmarking then means the creation of such a person note in the same way as all his existing person notes already are. If it’s a recipe it pulls out the recipe, converts cooking terms and measures to Dutch terms and measures, and makes the ingredients available to dump into a shopping list.
- Similarly everywhere he has a ‘copy to clipboard’-button in his Theta, it has a contextually determined template, so he can paste it into something else in the way he needs it at the destination. I use those templates in different places already, the way I send a bookmark to my blog, my annotation tool, and how an annotation is imported into my Obsidian notes, how I save a webpage in markdown to my notes, are all determined by a template that takes the same basic information but styles and orders it differently based on purpose and destination.
- That contextualisation sometimes needs persistent data from outside. He incorporates such data into his local database. E.g. all the place names for the Netherlands, so he can recognise a place name in his own material, or search with any of them across his material. Or the list of translated cooking terms mentioned above.
- He created his own e-mail client interface (using IMAP to access his mail accounts). This allows him to create processing geared to his own routines. E.g. a button to process an e-mail as a hotel reservation, or as parcel delivery announcement, or to pull location or event data from etc. That information then surfaces in his dashboard where it is made useful. It resulted in a rather long row of specific processing contexts but I can definitely see the power of it. Like I tinker with my ‘ideal feedreader’, doing the same for an ‘ideal e-mail interface’ where the point is to not let things reside in e-mail but make it findable and useful outside of it makes a lot of sense. And again, because you are predictable to yourself it is obvious what ‘outside’ means in each instance.
- He created ‘companion apps’ (using Mac’s Xcode to make them for iOS, I wonder if something similar for Android exists) for his phone, allowing him to access and work with information on the go.
On the train home, I started exploring both sqlite and node.js in more detail, to figure out if and how I may want to add it to my local personal tool set.
Can I use this to reignite my work on my personal toolsuite? That work is more aimed at facilitating myself in my processes and helping me achieve outputs.
Despite going to bed late, I woke unexpectedly early, given the holidays and weekend, and felt the need to explore more. So the session definitely kicked something in gear. It does need my personal approach of course, and I have plenty of relevant notes on this from the past years to use for it. Years ago, back in 2017, I already gave the effort a name too, Aazai.
I set up sqlite and node.js this morning to have a sandbox to try some building blocks out.
 English