I mentioned wanting to automatically add related blogposts based on comparing embeddings. When Dries Buytaert blogged about it, I wanted to follow his example. However I want to use those embeddings not just on this site, but also in my notes that include a local blog archive. That way I can quickly find related postings or notes with what I am writing/thinking. Embeddings are a numerical vector representation of the contents of a blogpost. You then find related blogposts by comparing those numbers across postings. Two weeks ago I set up the blog archiving.

Today I used the local archive of blog posts to calculate the embeddings. I wanted to calculate the embeddings on my local machine. When I write a blogpost and it gets stored in my local archive that should trigger calculating the embedding. Which I can then re-use in my notes or on my site.

There are multiple models available for local use to calculate embeddings, and I wanted to test which one seems most effective.
I installed three models in Ollama locally, and ran my complete blog archive through them:

  1. Nomic-embed-text-v1.5, which took 5 minutes to get through my blog archive, a US model by Nomic
  2. bge-m3, which took 12.5 minutes, a Chinese model by BAAI, Beijing Academy for AI
  3. qwen3-embedding:0.6b, which took 25 minutes, a Chinese model by Alibaba Cloud

The processing time difference across all three models is a factor 5, but that is mostly only relevant this first time when I run the entire archive (or when I need to redo that). From now on, only newly written or edited existing postings will have to have their embeddings (re)calculated. The time used for a single posting is insignificant whichever model I use (the slowest model took about 0.4 seconds for a blogpost, the fastest about 0.1).

Using Nomic I noticed that it handles language as a dominant distinction, meaning a Dutch post will only ever have Dutch language related postings, and German postings only German language ones. While there are topics that will likely indeed stay within the context of a single language, many of my Dutch postings are talking about things I also write about in English a lot. So Nomic is off the list. The other two models were created with multi-linguality in mind.

To compare the remaining two, I looked at 25 or so postings, and compared the first 10 related postings both models gave me. I intend to only ever show at most 5 related postings, if any, but looking at the first 10 gives an opportunity to see what else the embeddings calculate as relevant. Bge-m3 was slightly better at showing indeed related postings in the top 5. Qwen3-embedding worked well enough in the top 5 too and was stronger further down the list, where Bge-m3 started showing more clearly unrelated postings further down. There the Qwen model would find relations to things mentioned in longer blogpostings that Bge missed but I see as relevant. So I can use either for showing the most likely related blogposts on my blog, with bge-m3 being the smaller and faster model to calculate embeddings.
On the other hand, in my notes when writing, the Qwen model would work better if looking at entire blogposts. However, I don’t intend to make comparisons there to full length blogposts, but to paragraphs in long blogposts. There are 264 blogposts longer than 800 words (their average is 1200 words. Thirteen over 2000 words, the longest 2850 words, often talk transcripts) Then the difference between the two models will dissolve again. For now I am going forward with Bge-m3.

A concern is there might be model drift, even if always nominally using the same model. This can only happen if I update the model locally, and then it is needed to check against known results whether there has been drift. I have the current embeddings, so occasionnally recalculating a few and compare as well as logging a few good results to see if they still hold would be enough. The remedy for such drift when it influences results too much is to recalculate all embeddings again. That, as shown above, can be done fairly quickly. Something to add to the maintenance note for this set-up.

The next stage is building a way of storing / pushing the embeddings to this blog and in my notes, and write the php script (based on what Dries created) that does the comparisons both on my site and across my notes.

Y is currently learning European countries and their capitals for school. Of the 45 country/capital combinations to be learned on a blind map, 24 will be tested next week, and the remaining 21 two weeks later. Self study, or with our help, can mean that less well remembered combinations don’t get the attention they need. And where we help she only provides answers and does not see the writing of a name.
Y also likes to practice more than what we can give her in time.

This morning I thought that this was a good option to create a card deck for spaced repetition for her, and install Anki on her (Linux) laptop.
Anki’s data structure is not hard, and the material in this case has an even easier structure (numbers as map reference, country names and city names).

The blind map however was a bit harder to include usefully. The map is not very large, with small numbering. On top of which came that the teacher had made three mistakes numbering some of the Balkan countries. Two were corrected with pen by Y, one was uncorrected. Scanning the map also gave a not very satisfying result in terms of contrast, and there was a folding line through the map as well.

The scan of the map, with manual corrections
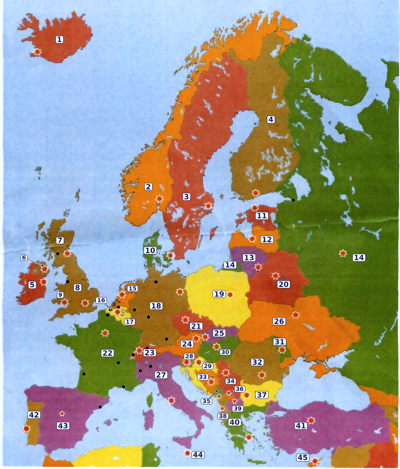
My graphical skills are non-existent, so I started up Claude to improve the image in terms of contrast and legibility. It did, after which I went through the map to verify no mistakes were introduced.


The map with improved contrast and the numbers all replaced in black lettering in a white box.

With the map improved I used it in the template for the Anki cards. I made a note type ‘Europe map’ with the three fields I mentioned, and imported the list of 45 countries into it. I also made an additional note type, namely for groupings of countries. Just a few for now. Creating chunks like that (the Baltics, the BeNeLux, Scandinavia, UK, the Irish island) is another way to make memorising easier. Chunking was not part of how the material was handed to Y, but something I added. Especially chunking the three Baltic countries is useful to tell them apart. They are positioned north to south in alphabetical order.

I created three card types for each country and capital.

  • Which country is number X on the map, and what is its capital? (and the grouped version ‘Which countries are the numbers X,Y,Z on the map?)
  • What is the capital of [country]?
  • [capital] is the capital of which country?

All three card types show the map image as well.

Getting Anki properly installed on Y’s Linux Mint laptop was the biggest hurdle it turned out. The package manager on Linux Mint is tied to outdated versions of Anki, so I had to install it through the terminal after first manually installing a range of additionally needed libraries. The Anki documentation helped. It shows once more how Linux is not a consumer ready OS (mostly because of the variety of Linux distributions, no way any app builder can easily deliver one-click installers for all of them.)

When I picked up Y from school this afternoon, I explained what I made as we cycled home.
She immediately tried it out. In the next few days we’ll see how it works for her.

Das Biblionetz ist eine einzigartige Website, die mehr Aufmerksamkeit verdient. Es beschreibt viele tausende Bücher, Artikel, Texte und Ausschnitte, und deren Verbindungen und Zusammenhänge auf Grund von Begriffe, Erwähnungen, Fragen und Aussagen.


Ein Beispiel wie Texte im Biblionetz untereinander verknüpft sind, und diese Vernetzung navigierbar macht

Bereits 1996 hat Beat Döbeli (blog) das Biblionetz angefangen. Seitdem wird jedes Sachbuch und Artikel das ihm interessiert darin aufgenommen. Wie bei allem was man über Jahre hinweg konsistent macht kommt etwas dabei ‘raus das durch das erreichte Volumen eine ganz andere Qualität bekommt.

Vor einigen Jahren bin ich über das Biblionetz gestolpert. Seitdem verwende ich es immer wenn ich eine Frage habe über deutschsprachige Bücher. Als Niederländer habe ich den leichtesten Zugang zu Sachbüchern auf Niederländisch und Englisch. Aber, wie bei Französisch und Spanisch, ist das deutsche Sprachgebiet groß genug um eine ganze andere Bücherwelt zu bieten die für andere Sprachgebiete unsichtbar bleibt. Döbeli hat zwar andere Interessen als ich, aber wir teilen auch Interessen, und das heißt das das Biblionetz sowohl genügend Bücher enthält die ich noch nicht kenne, als auch Bücher die ich bereits kenne. Durch die Verbindungen zwischen Bücher und Konzepte kann ich, startend mit was ich kenne navigieren und (wenigstens für mich) interessantes Neues finden.

Selbst mache ich seit ich schreiben kann Notizen, und seit 1991 auch digital. Mit der Zeit hat sich das zu einer persönlichen Wissensmanagement Methodik entwickelt. Personal Knowledge Management (PKM) ist deshalb auch ein Interesse von mir seit vielen Jahren. In 2024 wurde in Utrecht (NL) die erste Europäische PKM Konferenz organisiert. Um zu helfen Sprecher und Teilnehmer zu finden aus unterschiedlichen Europäischen Ländern habe ich mich beim Orga-Team gemeldet. Und dann auch Beat Döbeli eingeladen um sein Biblionetz zu zeigen und über seine Erfahrungen zu erzählen. Leider konnte er bis jetzt nicht, da die Konferenz immer zusammenfiel mit einer wichtigen Fachtagung für ihn. Im nächsten Jahr, 2027, wird es dann klappen. Wer an PKM interessiert ist sollte die Konferenz schon mal im Terminkalender vermerken (12. und 13. März 2027).

Darüber und mehr haben wir gesprochen als wir uns im Juni zum ersten Mal trafen, in Zürich. Wir sprachen über die Anfänge von Biblionetz und was es jetzt für ihn in seiner Arbeit als Professor an der Pedagogische Hochschule Schwyz bedeutet. 1996 war er als Informatiker an die Entwicklung des WWW interessiert, und betrachtete was er met Biblionetz anfing nicht direkt als Akademiker. Jetzt verwendet er das Biblionetz als ein akademisches Werkzeug, indem er zB. Studenten und Kollegen leicht mit Leselisten versehen kann. Bereits am Anfang war ihm klar das es mal eine Zeit geben könnte wo Computer das was er sich mit Biblionetz gebaut hat als persönliches Werkzeug, auch von sich aus machen könnten. Jetzt mit KI ist die Zeit vielleicht angebrochen.

Das Biblionetz ist über RSS zu folgen (wie natürlich auch Beat Döbeli’s Blog)

Dieser Blogartikel ist ein Beitrag an den Blogwochen 2026, im Thema ‘Mensch/Projekt der/das mehr Aufmerksamkeit verdient’.
Die Blogwochen, von Mitte September bis Mitte Dezember, sind dazu gedacht mehr deutschsprachige Blogger sichtbar zu machen, und neue interessante Blogs für den eigenen Feedreader zu finden. Ich nehme Teil weil ich mehr auf Deutsch schreiben möchte, und auch die Anzahl der deutschsprachigen Blogs die ich in meinem Feedreader folge vergrößern möchte.

Last March I made an export from my blog, so that I have all my blogposts since 2002 (some 3800 posts) in my notes locally. This makes it easier to find and link to my own blogposts while I am working, thinking, or writing in my notes. What I did not do in March was set up a way to keep syncing my blogposts to my notes from then on. Meaning I am now 6 months and 60 blogposts out of date.

Meanwhile Dries Buytaert wrote a month ago about how he used embeddings to list related postings with a blogpost based on their content, not their tags, keywords or categories.
This sounded immediately interesting and useful. What he describes is to run your site content through a model to create embeddings (a range of numbers as vectors representing your text), store the embeddings, and have a local script that when a posting is rendered calculates which embeddings match your posting closest. Related postings then is when their numerical vectors are closer than others. Only initially when you calculate embeddings for a posting is this dependent on a LLM, and afterwards it’s all regular calculations.

I thought creating those same embeddings may also be useful for semantic search within my blogposts for myself.
The plan therefore now is to

  • set up ongoing archiving of my blog and parsing them to my local notes
  • create embeddings using a model locally through ollama, e.g. with bge-m3, qwen3-embedding:0.6b, or nomic-embed-text
  • use those embeddings to calculate related postings for each existing posting, and forwards for new postings
  • use those same embeddings to allow finding related postings in my notes when writing something

The archiving is set up now, and updated once every day.

Next step is building and testing different ways of creating embeddings. The model to make those must be able to deal with and compare multiple languages, English, Dutch and German. I need to use the same model across all embedding of old and new posts, and when I want to compare with something I’m writing in my notes. This as different models create different representations of the same text and are not interchangeable. Also earlier this week in London the topic of model drift came up, that the same model, if you use it through an API from a vendor, will get tweaked and change over time. This results in slowly shifting embeddings.
With the team at Activate Intelligence we talked about how you’d need to pin down a model, and also log what a good result looks like when you start using it, so that you can detect drift over time. Using a local model (not an online model through an API) reduces drift, as things stay the same as long as I don’t update a model on my machine.
Solving drift means recreating all embeddings, which is the same effort as creating them now is. So, it’s not a barrier, but it is maintenance you need to stay on top of.

Favorited Deconstructing A 17th Century Letter by Wouter Groeneveld (Brainbaking)

This type of thing is always highly fascinating to me. Using artefacts, here 17th century letters that survived to present day by happenstance and thus not having been delivered, to say something about life in those times, habits, language, and rituals. Now try and imagine AI slop being unearthed from a salvaged disk drive when they dig up some mysterious building that apparently was called a ‘datacenter’ originally, several lifetimes hence, and trying to glean any meaningful context from them. And come up blank. “That’s not a coincidence. That’s a key pattern.” Claude would undoubtedly generate. With ominous or pretentious titles (‘Why this matters’) for paragraphs.

Wouter mentions the academic book in question is available online for free. “Letters as Loot” by Gijsbert Rutten and Marijke J. van der Wal, was published in 2014.

The most interesting is the deconstruction of a typical 17th century letter, written by Angenieten Cornelis to her husband at sea Roelandt IJosten Ostvorndijck.

Wouter Groeneveld

I today replaced the last handful of embedded Flickr images with self hosted copies, that merely link back to the source at Flickr. This way I am certain that no tracking by Flickr is possible when you visit this site.

Five years ago, I stopped embedding Flickr images for new posts. I also started to replace existing embeds with self hosted copies. I did most of them within months, but a few dozen remained. Some because they held many images, others because they used images others had made (shared with a Creative Commons license). In both cases the slightly more work needed to replace them put me off. Every now and then I did a few. In the past month I brought the list of posts to change down to 10. And today I did the final 5.

My ‘I don’t track you here, but others might‘ statement, which I added in January 2020, has now therefore become fully fact and not just an aspiration. For all other services I had removed the embeds already. I can remove the ‘others might’ now.